Datasets built to order, from the hard parts of the public web.
Text-rich images, egocentric video, multilingual speech and human motion — sourced, annotated and evaluated for your training brief. The datasets below are our portfolio; yours is the product.
custom builds · private evals under NDA · provenance-verified
Live annotated samples load here. The full viewers live on the dataset pages.
Explore multilingual images, or switch to our annotated video collections. Open the full sphere →
On the shelf, built end to end
Explore real annotated samples, dataset specifications and the available quality checks for each collection. Use them to shape the scope of your own build.


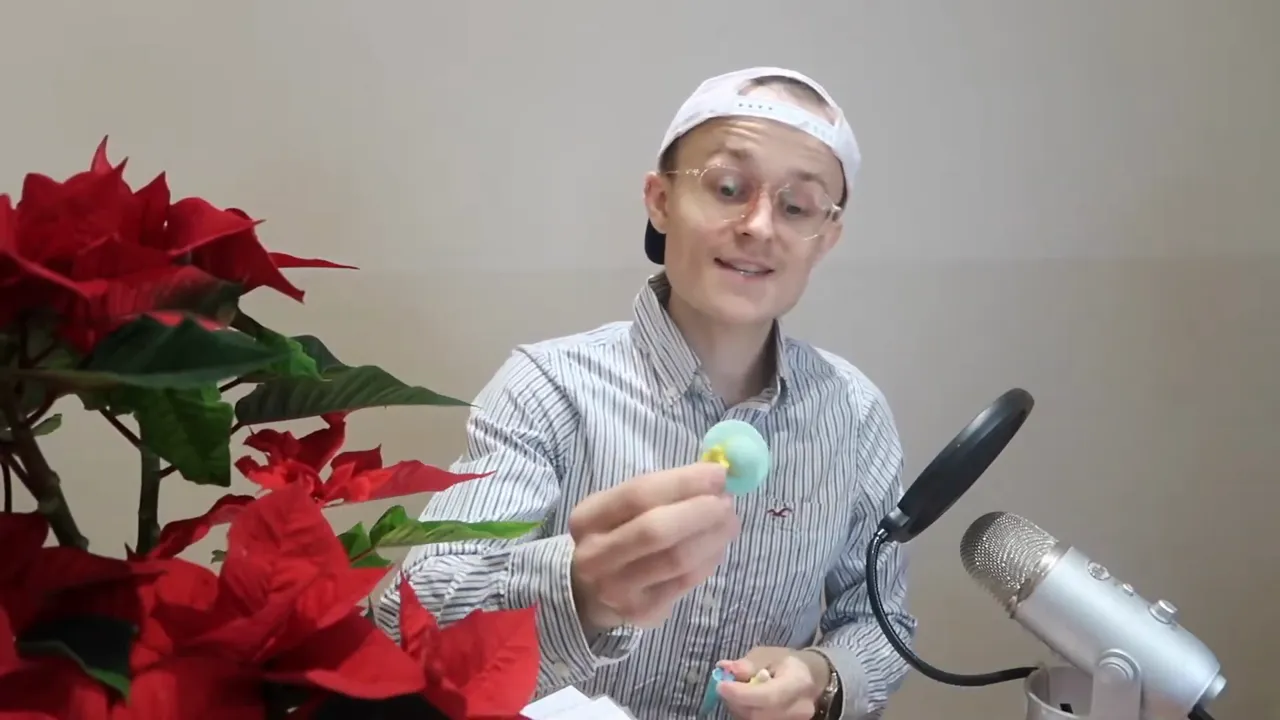
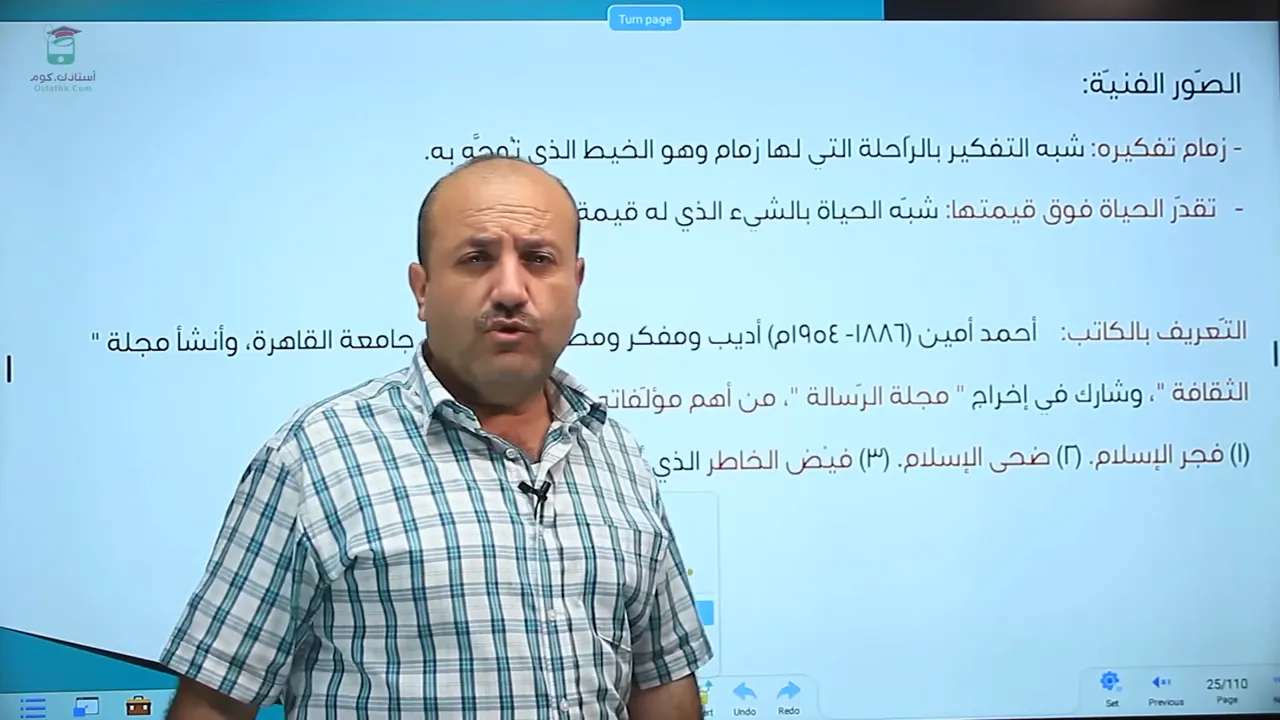

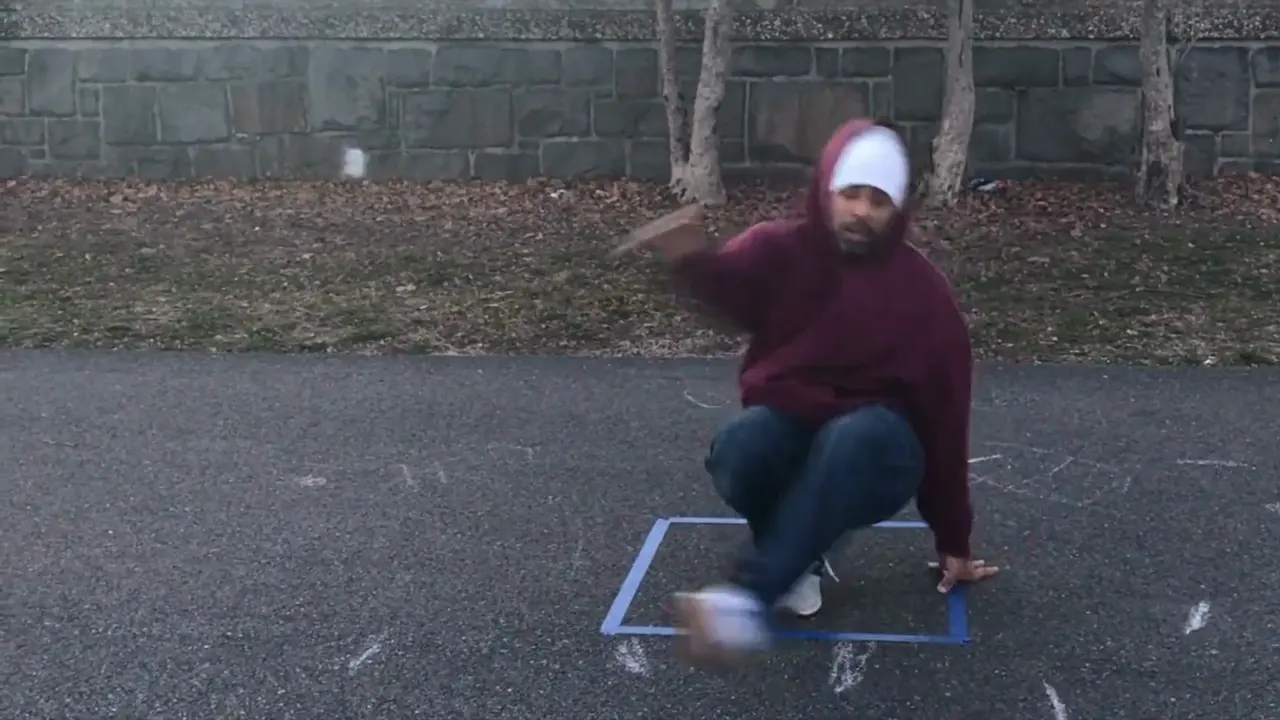
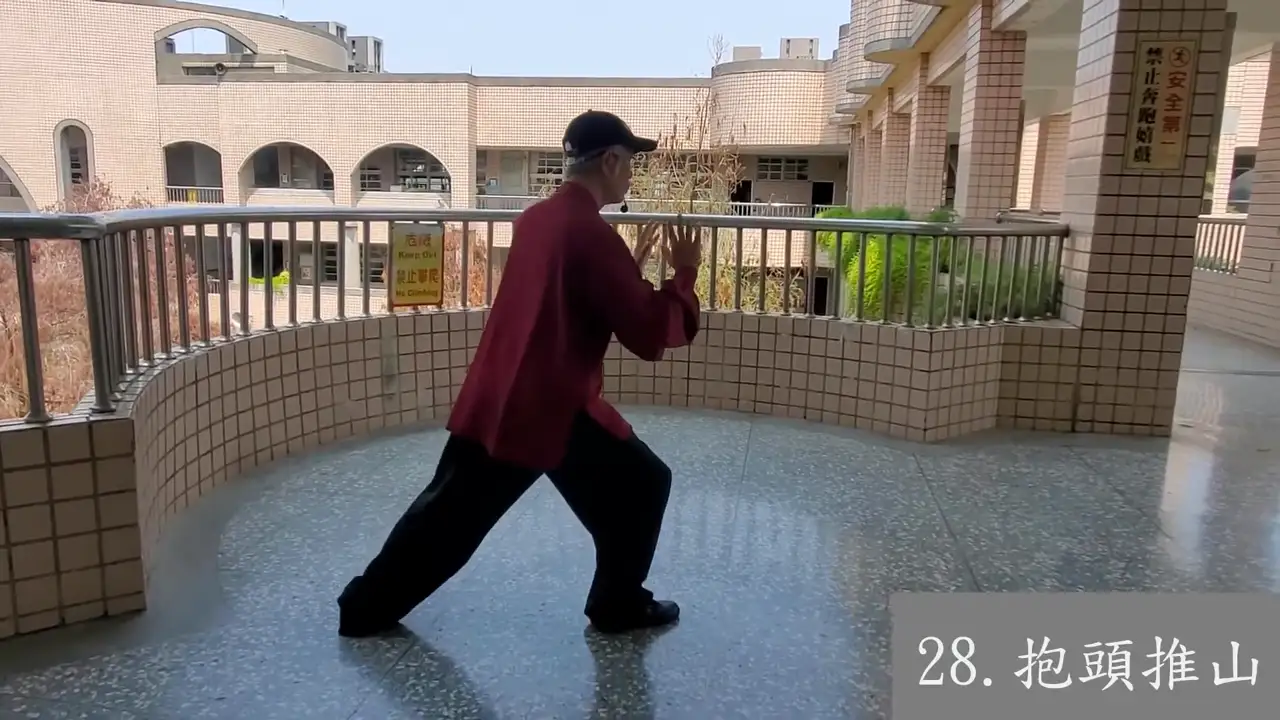

Custom is the product
The interesting datasets rarely exist yet. Brief us on modality, domains, languages and volume — we build to spec with the same funnel, annotation stack and QA you see in our own lines.
- 01 Brief
One email: modality, domains, languages, volume, annotation depth, deadline.
- 02 Sample in ~48 hours
A free eval slice with full annotation — run it through your pipeline and measure.
- 03 Pilot in 1–2 weeks
Staged delivery with an accuracy SLA verified on an agreed golden set.
A funnel, not a firehose
Cheap filters first, expensive ones last: most candidates are rejected from metadata, thumbnails and embeddings alone, before a single full video is downloaded. Pass rates below are from a recent production run.
- S0 79% Metadata gates pass rate on duration, language and live-status checks — the cheapest filters run first
- S1 82% Frame & embedding probes storyboard frames + viewpoint/domain embedding classification, still with no full download
- S2 33% Shortlist for full download only top-scoring candidates are ever fetched at full resolution — 732 of the 3,479 videos discovered
- S3 ×5 Lossless cutting each downloaded video yields multiple candidate procedure clips
- S4 ≈13% Final curation of cut clips survive balancing by domain, viewpoint, resolution and leakage screening
Full methodology — QA gates, golden sets, leakage screening — documented here.
Measured, not promised
Measured on golden sets during real annotation runs.
Every record can explain itself
Training data is an asset only while its rights story holds. We collect from the open public web and document origin down to the individual record.
- source URL
- exact license
- fetch timestamp
- transform hash
- dataset card / datasheet
- QA report with golden-set metrics
- SHA-256 manifest, verified at acceptance
Due-diligence questionnaires answered on request. License filtering to your requirements is part of scoping.
Talk to the people who build the pipelines
You reach the engineers directly: straight answers about coverage, formats, licensing and feasibility, and a private eval if it fits.